
ai
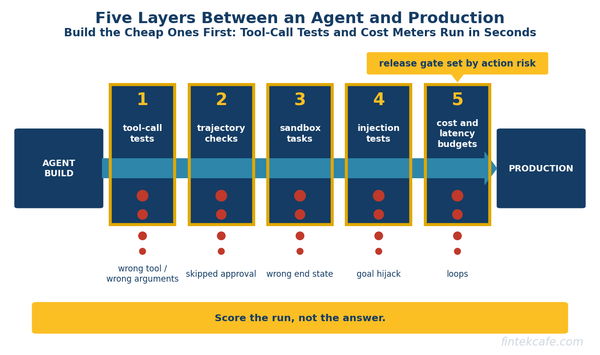
How to Test an AI Agent Before It Touches Production
Agent evals must score a sequence of actions, not one answer. The five test layers, pass^k reliability, graders and release gates by action risk.
Agent evals must score a sequence of actions, not one answer. The five test layers, pass^k reliability, graders and release gates by action risk.
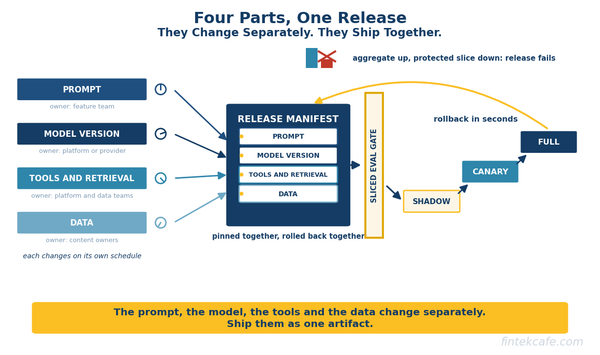
An LLM feature has four parts that change on their own. Release them as one versioned artifact behind an eval gate. The rules, tables and build order.
The durable moat in applied AI is not the model. It is the eval suite: the one asset competitors cannot rent, and the one due diligence should price.
Most teams ship LLM features with no real evals, then find failures in production. A practical framework for an evaluation harness that scales.

Most enterprise AI failures are eval failures, not model failures. Learn the three eval tiers, the golden-dataset problem, and an eval maturity model.
Deep analysis across the systems, strategies, and economics that shape modern technology.
Premium Members Get: Exclusive deep-dive research · Architecture playbooks · Executive briefings · Full archive access