
ai
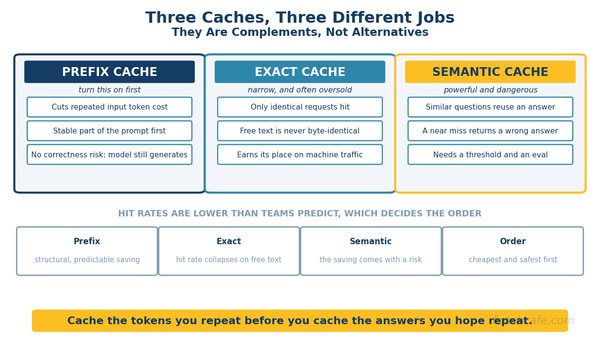
LLM Caching: Exact, Prefix, and Semantic, and What Each Actually Saves
Three LLM cache types solve different problems teams routinely conflate. What each saves, the hit rates you should actually expect, and where each one breaks.
Three LLM cache types solve different problems teams routinely conflate. What each saves, the hit rates you should actually expect, and where each one breaks.
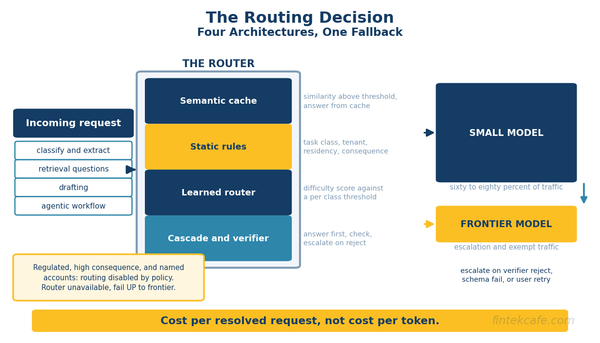
Route 60-80 percent of production traffic to small models with a quality fallback. The four routing architectures, the eval signals, and the failure modes.
Frontier models do not win every task. A 2026 framework for when small and mid-sized models beat them on cost, latency, privacy, and accuracy.
Per-token prices look comparable. They are not. Three hidden cost drivers reshape the real LLM inference economics for enterprise buyers in 2026.
Deep analysis across the systems, strategies, and economics that shape modern technology.
Premium Members Get: Exclusive deep-dive research · Architecture playbooks · Executive briefings · Full archive access